Every business
runs on documents.
DocxIntel turns them into understood, approved and executed work — with the complete AI engine running inside your own environment. Scroll to follow one contract through it.
The enterprise workspace for document-driven work.
DocxIntel helps enterprises create, understand, review, approve, sign, execute and monitor document-driven work. Open the Overview and you see what is happening, what needs you, what AI has completed and what it can do next.
Good afternoon, Admin
Here's what needs attention across your workspace.
Needs attention
12
items need your action
Approvals
4
assigned to you
AI ready
6
drafts awaiting confirmation
Risks
3
open findings above threshold
Needs your attention
- Offer — Rahul SharmaManager approval required · Pending approval · Due todayReview
- MSA — ABC Corp3 commercial deviations detected · In review · Due ThuReview findings
- Invoice — Vendor XPO amount mismatch · Exception · Due todayResolve exception
- SOW — Client YSignature pending from customer · Sent for signature · Sent 2d agoOpen signing
Work in progress
3 active · 1 blocked · 2 due today
SOW — Client Y
Blocked: legal approver on leave — delegate to unblock
Department workload
- BDA
- HR
- Legal
- Finance
- Procurement
AI work completed · this week
Processed by the private DocxIntel engine
142
documents analysed
86
fields extracted
24
documents classified
18
drafts generated
7
risks detected
11
approval packages prepared
Understand every document — with evidence.
Ask, Analyse, Identify, Classify and Compare. Every result shows its source, its confidence and the next human action — and every one runs on the private DocxIntel engine inside your infrastructure.
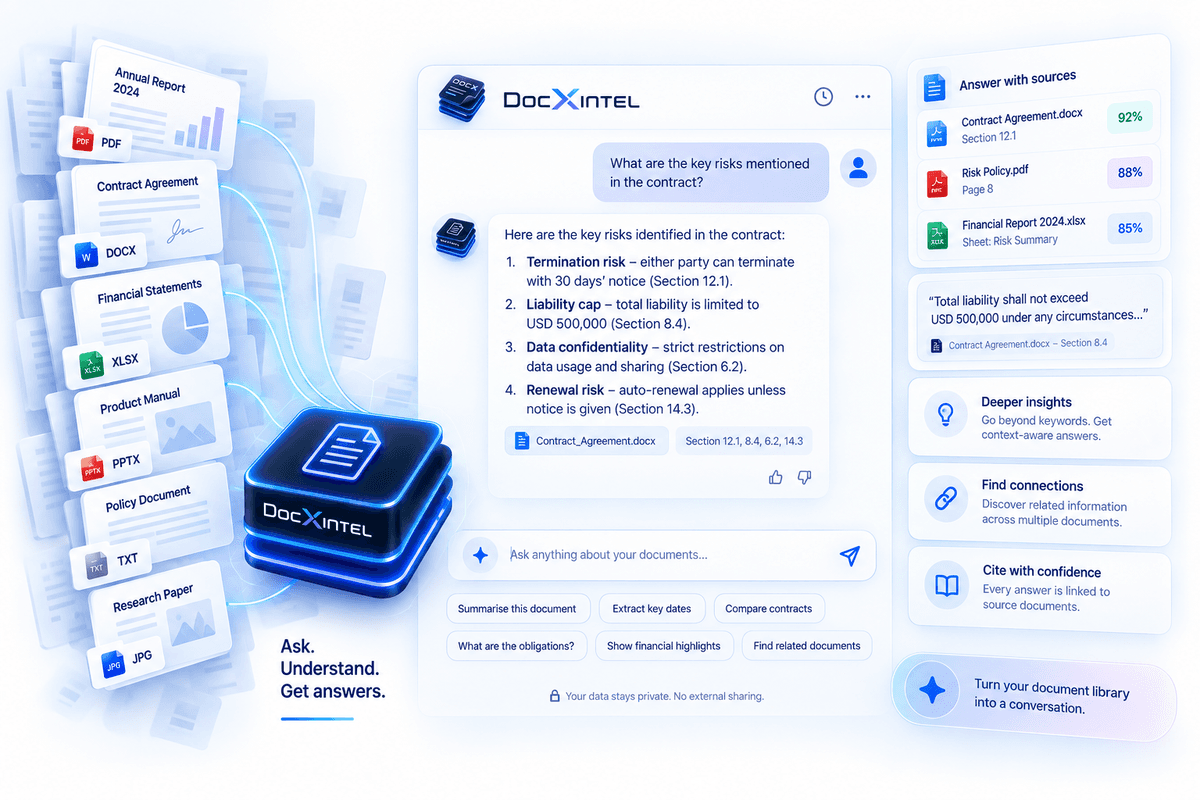
Ask, and see exactly where the answer came from
Ask in plain language across every document you are permitted to see. Every substantive answer shows its source documents and evidence — and if the documents do not support an answer, DocxIntel says so.
- Answers cited to the document, page and passage
- Permission-aware: only what you are allowed to read
- An honest "not supported" instead of a guess
From the document that arrives to the work that gets done.
BDA / Sales · starts with: Customer requirement
Requirement
System
Extract scope
AI
Draft proposal
AI
Review
Person
Approval
Person
Signature
Person
CRM update
System
A proposal or SOW drafted from approved templates and pricing, approved by policy, signed by the customer and pushed to the CRM.
Blue steps are done by AI on the private DocxIntel engine. Amber steps wait for a person. Every step is recorded, and nothing leaves your environment.
You don't get an API key. You get the whole engine.
Every model DocxIntel uses — OCR, embedding, reranking and reasoning — is our own, and every one of them is installed on your hardware. Documents travel from your storage to the engine and back, and the path never crosses your perimeter.
DocxIntel private AI engine
OCR
Proprietary
Embedding
Proprietary
Retrieval
Private index
Reranking
Proprietary
Reasoning
Proprietary
Document intelligence
Fields, clauses, risks, citations
Workflow & agent
Review, approve, sign, execute
Business action
In your systems, with an audit trail
External AI providers: not required, not called. Outbound AI requests in a default install: 0.
Ten components, one deployment, all on your servers
- OCR engineArabic and English print, handwriting, stamps and degraded scans.
- Embedding modelSemantic representation of every page, computed locally.
- Reranking modelOrders retrieved passages by relevance before reasoning.
- Reasoning modelAnswers, drafts, comparisons and risk calls, with citations.
- Parsing engineLayout, reading order, tables and multi-document splitting.
- Document intelligenceFields, entities and clauses with page and coordinates.
- Search & vector storeHybrid keyword and vector retrieval inside your network.
- Workflow engineReview, approval, signing and execution steps you define.
- Agent engineCarries out multi-step document tasks under your permissions.
- Audit & governanceWho did what, to which document, and on what evidence.
99% field-level accuracy — including where it is lower, and why.
Measured on the private engine, on a set built to break extraction tools: 42% of pages carry Arabic script and fewer than a quarter are clean digital files. Every field is in the denominator; nothing unreadable was dropped.
99.0%
Field-level accuracy
exact match, every field counted
99.7%
Straight-through accuracy
after 2.3% routed to review
96,300
Fields adjudicated
double-keyed human ground truth
76%
Scans, photos and faxes
of 3,140 documents in the set
- Native PDFs and office documents99.9%review 0.4%
- Bilingual Arabic–English tables99.5%review 1.1%
- Stamped and signed invoices99.4%review 1.6%
- Phone-camera photographs99.1%review 2.4%
- Arabic handwritten forms98.1%review 5.2%
- Multi-generation fax copies97.2%review 7.8%
Exact match on normalised values against human-adjudicated ground truth, 3,140 documents and 11,480 pages. This is evidence of method, not a warranty for your documents — the threshold we contract to is measured on your own set during a Proof of Value.
These are the documents that break everything else.
Skewed phone photos, handwritten Arabic, stamps over printed text, fourth-generation faxes — the documents most extraction tools quietly route to a human. DocxIntel reads them by default.
Handwritten Arabic prescription
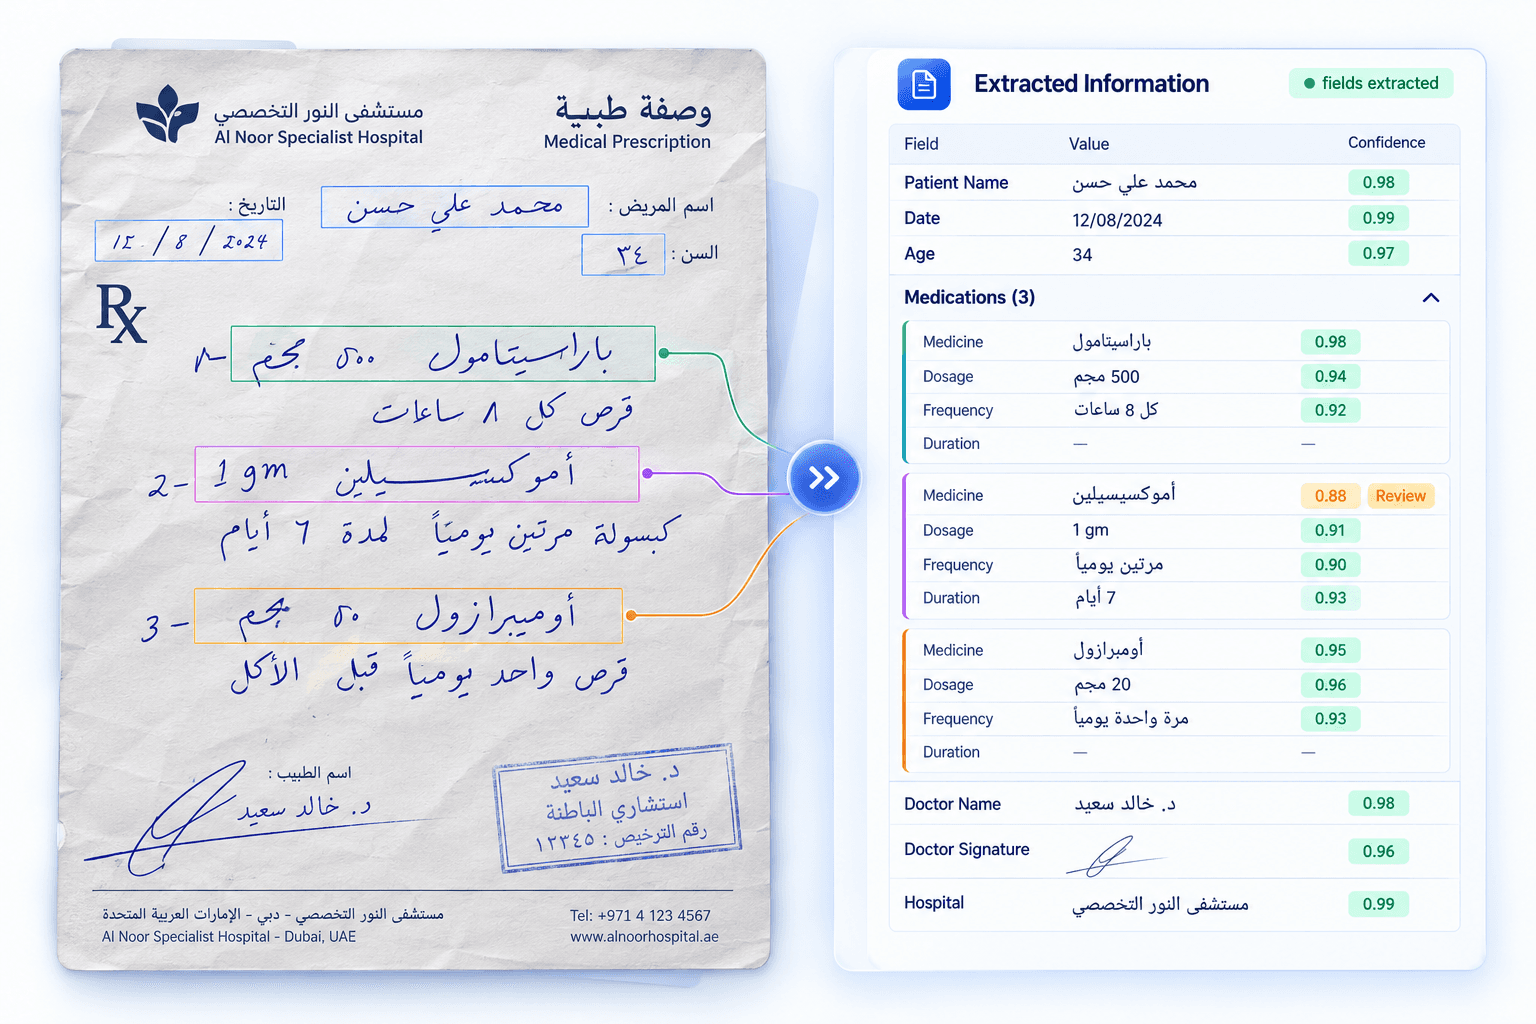
Cursive Arabic script and a doctor's shorthand — read like a pharmacist would, not a scanner.
Phone photograph — skewed, shadowed, at a counter
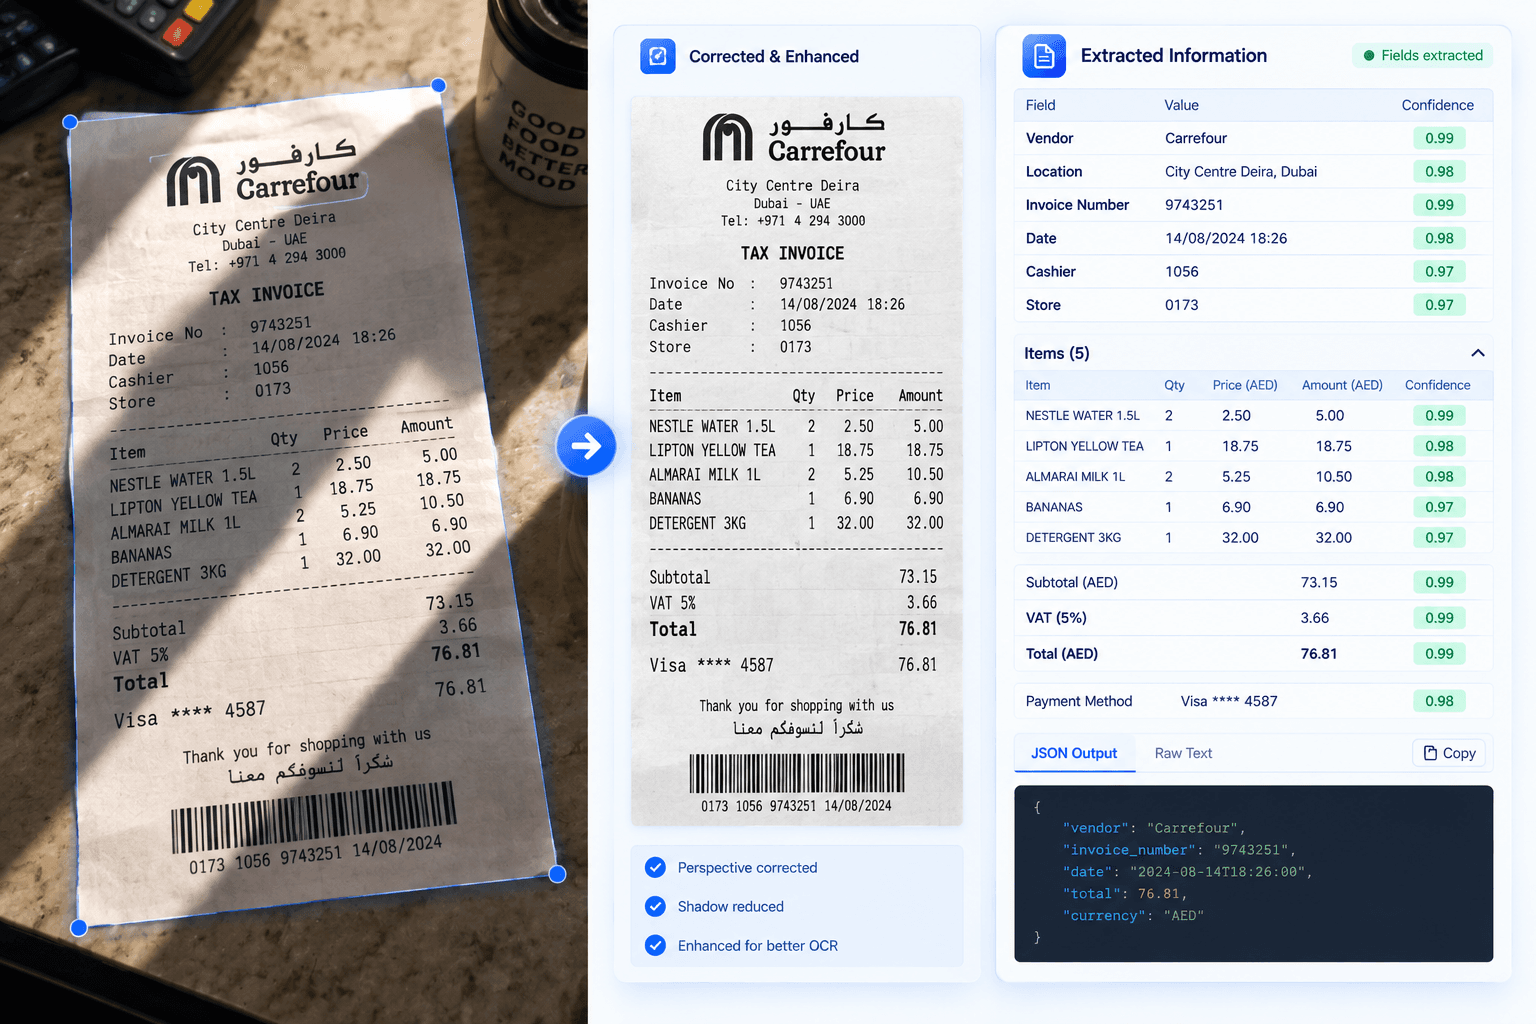
Deskewed, shadow-corrected and enhanced before a single field is ever read.
Mixed Arabic–English, one page
INVOICE / فاتورة
Bill To
شركة الأمل
Amount
4,250 AED
Script switches mid-line, sometimes mid-word — every field still resolves.
Stamp and signature over printed text
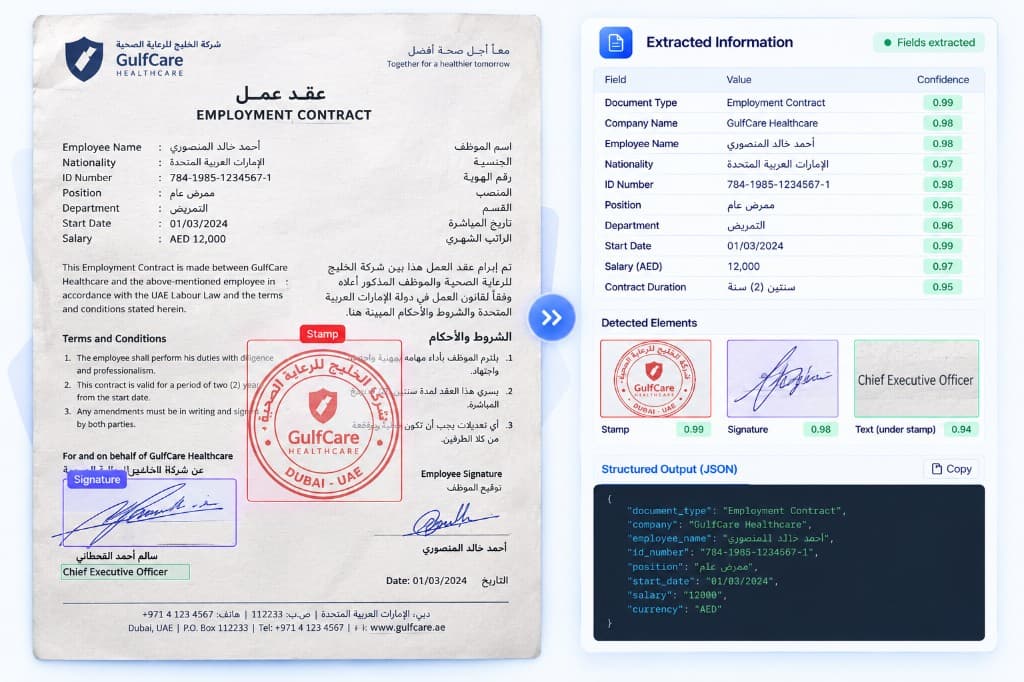
Ink, stamps and signatures overlap the very text they're meant to certify.
Multi-page claim packet, auto-split
One PDF, four unrelated documents — split and classified automatically.
Deploy it where your data belongs.
The same complete DocxIntel engine in every environment. Your data stays where you deploy it.
Your network perimeter
DocxIntel private AI engine
Trust that comes from where things run, not from a badge.
01
The boundary
Where your data is, and what can reach it
- Private deployment
- On-premise, private cloud or air-gapped
- Customer-controlled data boundary
- Documents never leave the configured environment
- Local processing
- Every model runs on your hardware
- Controlled external access
- External AI disabled by default; administrator controlled
02
The controls
Who can do what, with which model
- Proprietary AI models
- OCR, embedding, reranking and reasoning — ours, installed in yours
- Model control
- Versions pinned by you; updates validated before promotion
- Role-based access
- Per collection, per workflow, per action; SSO via OIDC or SAML
- Enterprise integrations
- Content systems, mailboxes, ERP, CRM — inside the boundary
03
The record
What happened, and who decided
- Human approval
- Workflows stop at the steps you mark for a person
- Audit
- Every read, answer, approval and agent action, with its evidence
- Governance
- The log lives in your estate, not a vendor portal
Fits the estate you already run — inside the boundary.
Documents arrive from the systems you already use, and results land in the systems that act on them. Every connection runs inside your environment.
Where documents come from
- SharePoint & Microsoft 365
- OpenText
- Alfresco
- Any CMIS 1.1 repository
- IMAP & Graph mailboxes
- SFTP drops
- S3-compatible storage
Where the work lands
- REST & gRPC API
- Webhooks
- Kafka
- ERP, CRM, HR & finance systems via API or message bus
- JSON, CSV, XLSX, searchable PDF
How you run it
- SSO via OIDC or SAML
- Role-based access
- Prometheus & Grafana
- Kubernetes or Docker Compose
- Python, TypeScript & Java SDKs
The full list ships in the deployment bundle — see what's in the box.
Built for the industries where documents can't leave the building.
Same platform, same on-prem guarantee — tuned to what each regulated industry actually processes every day.
Turn statements and filings into structured data — without a single page leaving your vault.
- Extract and validate data from statements, KYC files, and financial filings automatically.
- Give underwriters structured, verified fields instead of manual re-keying.
- Scale document volume without scaling headcount or exposure risk.
Meridian Bank processes 40,000+ statements a month with 99.2% field-level accuracy.
- 96%
Statement · Acct •••4821
Chase — Feb 2026
- 98%
KYC Form · Global Holdings Ltd
Beneficial ownership
- 94%
Wire Instruction · Ref #88213
SWIFT / IBAN verified
Field-Level Accuracy
99%
Faster Manual Review
5x
Documents Processed / Yr
2M+
Data Leaving Your Building
0
Trust shouldn't come from a logo you recognise. It should come from what you can verify.
So instead of asking for your confidence, we publish the evidence — open it and check for yourself.
Accuracy benchmark
Our numbers on Gulf documents — methodology and test set included.
What's in the box
Every engine component and model version you install — nothing undisclosed.
Security pack
SBOM, dependency scans, pen-test summary and data-flow diagram.
Reference architectures
Air-gapped, Azure UAE North, AWS me-central-1, bare metal.
Everyone else charges per page. Which means every page leaves your building.
Metered cloud parsing APIs run roughly $0.003 to $0.056 per page depending on mode — and on-premise, where it exists at all, is gated to enterprise tiers.
100,000 pages / month
1,000,000 pages / month
Where processing happens
On-premise
The questions you were already going to ask.
No sales deck required — here's what buyers ask before they trust a document intelligence vendor with their data.
No. Your documents, extracted fields and any feedback you give never leave your deployment and are never used to train, fine-tune or improve our models — for you or for anyone else.
Inference-only models — no data collection pipeline
Nothing sent to an external API by default
Contractually excluded from any future training set
Verifiable in the data-flow diagram we publish
The artifacts behind the claims
We publish what's finished, not what's planned. The security pack and regulatory mapping go up here the day they're ready.