Reads the page
Arabic and Latin script, print and handwriting, Arabic-Indic numerals, stamps over text, phone photographs and multi-generation faxes.
- Coordinates on every block
- Calibrated confidence
- RTL and bidirectional reading order
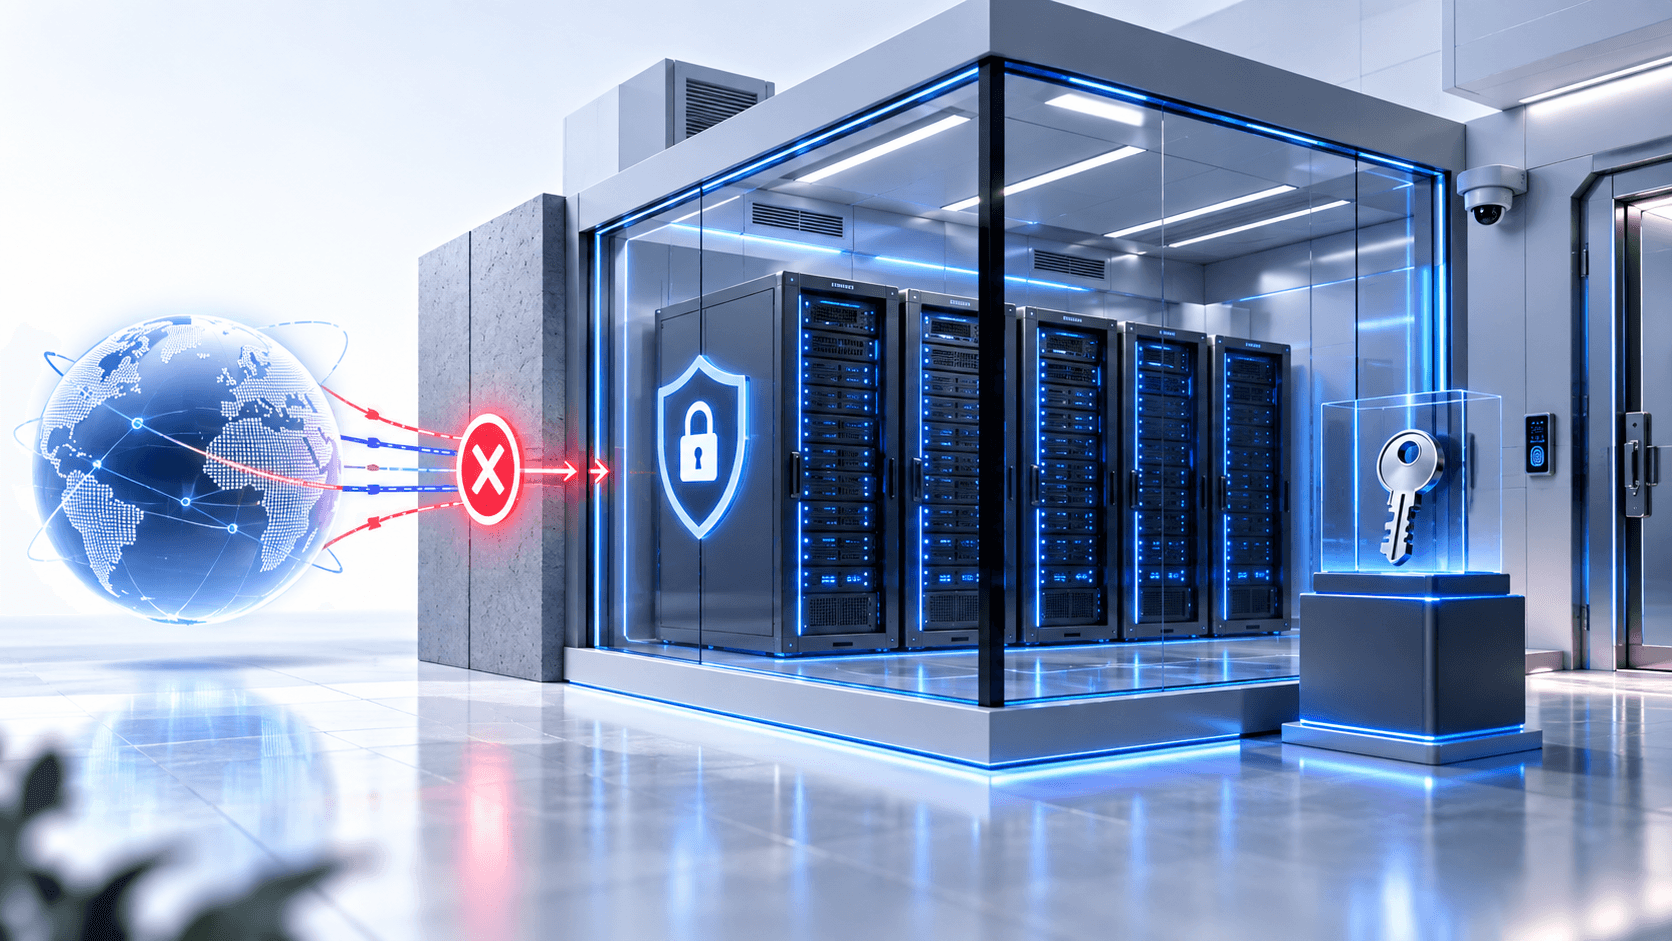
Most document AI is an API you send pages to. DocxIntel is the opposite: our proprietary OCR, embedding, reranking and reasoning models — and the parsing, intelligence, search, workflow, agent and audit engines around them — are installed inside your data centre or private cloud. Your data stays where you deploy it.
Accuracy is measured on the DocxIntel benchmark set with the methodology published on the accuracy page. The figure that binds us commercially is the threshold measured on your own documents in a Proof of Value.
Every model DocxIntel uses — OCR, embedding, reranking and reasoning — is our own, and every one of them is installed on your hardware. Documents travel from your storage to the engine and back, and the path never crosses your perimeter.
DocxIntel private AI engine
OCR
Proprietary
Embedding
Proprietary
Retrieval
Private index
Reranking
Proprietary
Reasoning
Proprietary
Document intelligence
Fields, clauses, risks, citations
Workflow & agent
Review, approve, sign, execute
Business action
In your systems, with an audit trail
External AI providers: not required, not called. Outbound AI requests in a default install: 0.
Each model does one job in the pipeline, and each runs on GPUs inside your boundary. None of them falls back to a hosted endpoint when a page is hard or the queue is long.
Arabic and Latin script, print and handwriting, Arabic-Indic numerals, stamps over text, phone photographs and multi-generation faxes.
Turns every page and passage into a semantic representation, in Arabic and English, so search finds what a clause means and not only the words it uses.
Reorders retrieved passages by real relevance before anything is reasoned over, which is what keeps answers grounded and citations precise.
Answers questions, drafts, compares versions, flags risks and prepares approval packages — every output tied back to the page it came from.
Layout, reading order, tables, and splitting multi-document packets into the documents they contain.
Fields, entities, clauses and classifications against your own schemas and taxonomy, with page and bounding box on every value.
Hybrid keyword and vector retrieval over the collections you choose to index, with access control per collection.
Review, approval, signing and execution steps you define, with confidence gates that decide what needs a person.
Carries out multi-step document tasks — gather, compare, draft, route — strictly within the permissions of the user it acts for.
Every read, extraction, answer, approval and agent action recorded in a log that lives in your estate, not a vendor portal.
Every step below happens inside your environment. The first six are the engine; the rest are your people and your systems, supported by it.
From a watched folder, a mailbox, object storage, your content system or the API — and it stays on storage you control from that moment on.
Normalised, deskewed and recognised, with every block carrying its coordinates and a calibrated confidence score.
Passages are embedded locally and written to the vector index inside your environment.
Hybrid search finds candidate passages and the reranking model keeps the ones that actually answer the task.
Extraction, comparison, drafting, risk detection or a cited answer — produced on your GPUs.
Every value and every answer carries its source document, page and region, so it can be checked in seconds.
Only what falls below your threshold is queued, with the source region highlighted.
On a prepared package of findings and evidence, with the decision written to the audit log.
The signed version is checked against what was approved.
Structured output and agent actions reach your core systems within the permissions you set.
Expiries, renewals and deadlines across the signed estate are watched, and owners are alerted.
Business users see one indicator: Private AI, running on your infrastructure. Platform and security teams get the full picture.
Detailed infrastructure metrics — GPU utilisation, throughput and queue depth — are exported to the monitoring stack you already run, using the dashboards and alert rules that ship with the deployment.
Both can read a document. Only one lets you tell a regulator that the document never left.
Where the page is read
Where embeddings and indexes live
Where prompts and answers are processed
Outbound AI requests
AI vendor in your data path
Works with no internet route
Cost of processing more pages
Describes the general architecture of hosted document AI APIs as of 2026. Individual services differ — ask any vendor, including us, for a data-flow diagram and verify it against your own egress logs.
What runs where, whose models they are, and what leaves your network.
They are ours. The OCR, embedding, reranking and reasoning models are proprietary to BizfyLabs and ship inside the DocxIntel deployment. There is no hosted model behind them: inference happens on the GPUs in your environment, and the engine has no code path that forwards a page, a passage or a prompt to a third-party AI provider.
A fixed-fee Proof of Value deploys the complete DocxIntel engine in your environment, measures accuracy on your documents and lets your security team watch the egress logs while it runs.